04
Why Corporate Proxies Make Some Websites Slower: Causes & Fixes
Corporate proxies can drag down site speed learn the why and how to fix it.
According to a 2023 network audit by NetMetrics, 42% of enterprise users report at least a 30% slowdown when accessing external web services through corporate proxies. That figure isn’t just a statistic; it translates into missed deadlines, frustrated employees, and lost productivity across dozens of departments. Imagine a sales team in Chicago trying to pull real‑time market data, only to watch the loading spinner spin for minutes while the proxy inspects each packet. The frustration is palpable, and the cost is measurable.
Common Challenges With Defining Why Corporate Proxies Make Some Websites Slower
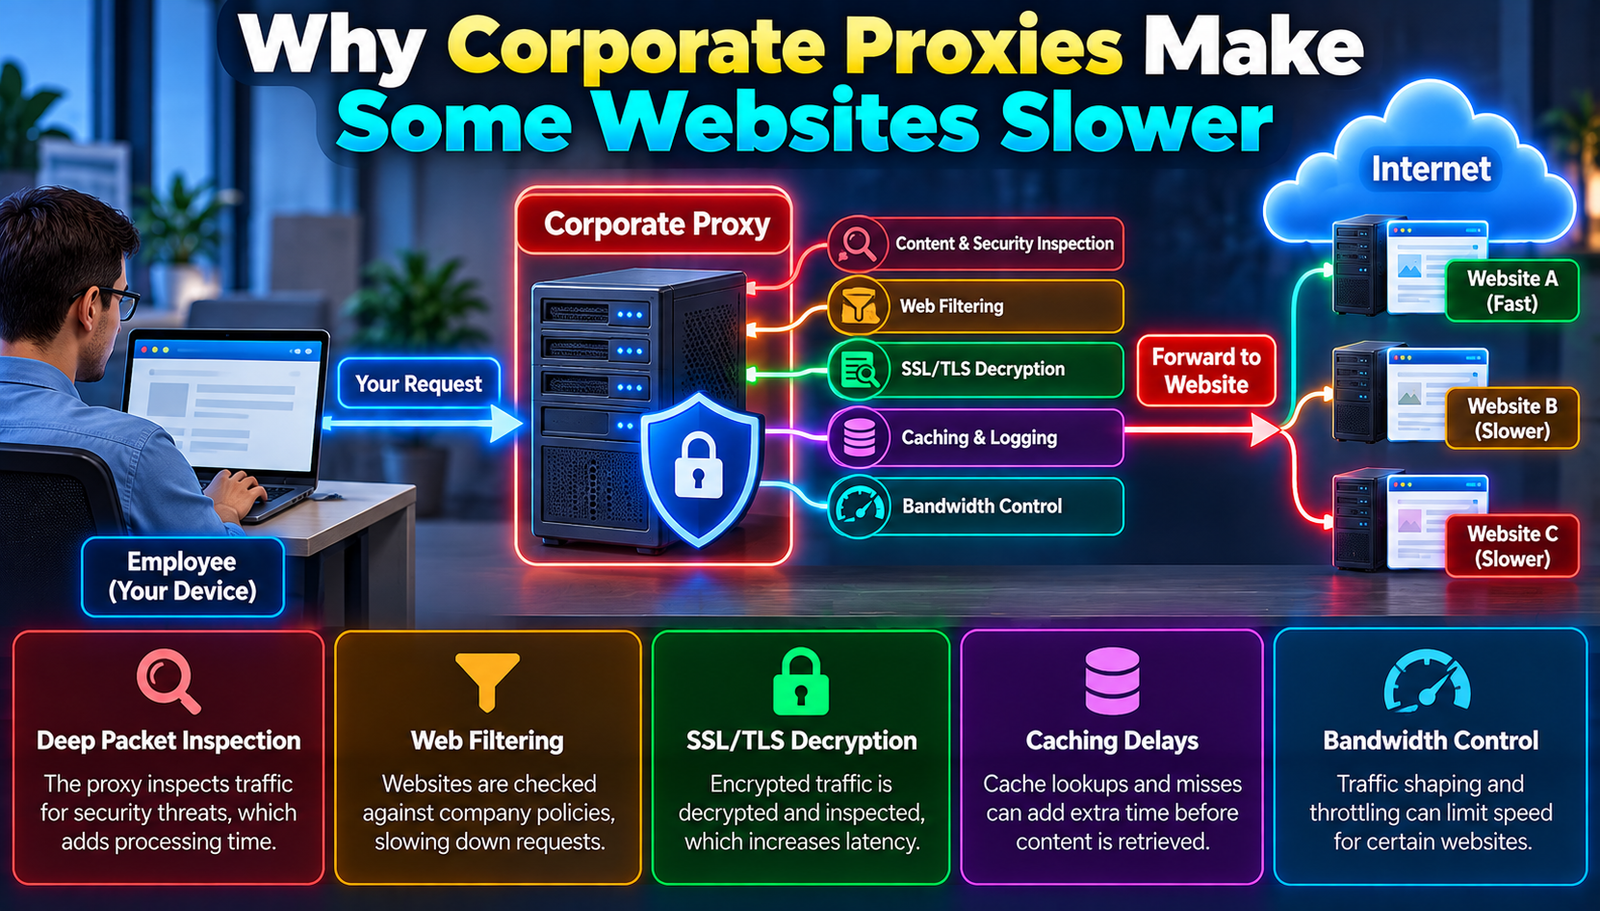
1. Excessive Content Inspection
Many security teams configure their proxies to scan every HTTP and HTTPS request for malware, phishing links, and data leakage. The scanning engines parse HTML, JavaScript, images, and even encrypted payloads. This deep inspection adds latency because each byte must be decrypted, analysed, and re‑encrypted before reaching the user.
The process sounds logical protect the network but it creates a bottleneck. When a proxy has to unpack a 5 MB video file, run it through multiple signatures, and then re‑package it, the round‑trip time can increase by several seconds.
2. Bandwidth Throttling Policies
Enterprises often impose throttling rules to curb bandwidth hogs like streaming services or large file downloads. While the intent is to preserve network resources, the same policies can unintentionally affect legitimate business sites that serve heavy assets such as product catalogues or interactive dashboards.
When a proxy applies a uniform cap say 2 Mbps to all outbound traffic, a data‑rich analytics portal may load half as fast as it would on a direct connection, frustrating users who rely on timely insights.
3. Inefficient Caching Strategies
Proxies are frequently used as caches to reduce repeat traffic to popular sites. However, misconfigured cache expiration times or overly aggressive cache bypass rules cause the proxy to fetch fresh content for every request, negating the speed advantage.
For example, a marketing team accessing a frequently updated blog might see the same page reload from the origin server each time, even though the content changes only once a day. The unnecessary round‑trip adds delay.
4. Geolocation Mismatch
Corporate proxies are often centralized in a single data center, sometimes located far from remote office locations. When a user in Dallas requests a site hosted on a CDN edge node in Seattle, the request is forced through the Dallas proxy, then across the internet to Seattle, and finally back to the proxy before reaching the user.
This detour adds extra hops, each with its own latency, and can double the time it takes for a page to become interactive.
5. SSL/TLS Termination Overhead
To inspect encrypted traffic, many proxies terminate SSL/TLS sessions, decrypt the payload, and then re‑encrypt it for the destination server. This double handshake consumes CPU cycles and memory, especially under high concurrent loads.
During peak hours, a proxy handling thousands of simultaneous connections may experience queue buildup, leading to noticeable slowdowns for end users trying to access cloud‑based SaaS tools.
Major Developments in Mitigating Proxy‑Induced Slowness
1. Deploy Selective Inspection Rules
Instead of scanning every packet, organizations can configure their proxies to apply deep inspection only to high‑risk categories such as executable downloads, unknown domains, or outbound data exfiltration attempts. This selective approach reduces processing overhead while preserving security for critical vectors.
Implementation steps include: (a) reviewing existing security policies, (b) tagging traffic by risk level using URL categorization services, (c) creating rule sets that bypass inspection for trusted SaaS domains, and (d) monitoring performance metrics to fine‑tune thresholds.
- Key Benefits:
- Reduced latency for routine web browsing
- Maintained protection for high‑risk content
- Lower CPU utilization on proxy hardware
2. Introduce Adaptive Bandwidth Allocation
Adaptive bandwidth solutions dynamically adjust throttling limits based on real‑time traffic patterns and business priorities. By integrating with a policy engine that recognizes critical applications such as CRM dashboards or ERP portals the proxy can prioritize those flows while still curbing non‑essential streaming.
To set this up, administrators should: (a) identify mission‑critical URLs, (b) define QoS tiers in the proxy’s traffic shaping module, (c) enable auto‑scaling of bandwidth caps during off‑peak hours, and (e) regularly audit usage reports to ensure fairness.
- Key Benefits:
- Optimized user experience for essential services
- Continued control over overall network consumption
- Automatic adjustment reduces manual policy churn
3. Optimize Caching With Content‑Aware Policies
Modern proxies support content‑aware caching that respects HTTP cache‑control headers while also allowing administrators to override expiration for static assets like images, CSS, and JavaScript libraries. By fine‑tuning these settings, the proxy can serve cached copies for high‑traffic static resources while always pulling fresh data for dynamic pages.
The process involves: (a) auditing current cache hit ratios, (b) mapping static asset domains, (c) setting longer TTLs (time‑to‑live) for those assets, (d) enabling cache‑bypass for API endpoints, and (e) validating performance gains with load‑testing tools.
- Key Benefits:
- Higher cache hit rates for repeat requests
- Reduced outbound bandwidth consumption
- Faster page load times for static‑heavy sites
4. Deploy Distributed Proxy Nodes
Instead of a single, monolithic proxy, enterprises can roll out a fleet of edge proxies located closer to remote offices or cloud regions. This reduces the physical distance data must travel, cutting round‑trip latency dramatically.
Implementation steps include: (a) selecting a lightweight proxy appliance that supports clustering, (b) provisioning nodes in regional data centers or cloud edge locations, (c) synchronizing policy sets across the cluster, (d) configuring DNS‑based routing to direct users to the nearest node, and (e) monitoring latency improvements with real‑time dashboards.
- Key Benefits:
- Lower network hop count for remote users
- Scalable architecture that grows with the organization
- Redundancy improves reliability and uptime
5. use Hardware Acceleration for SSL/TLS
Specialized SSL/TLS offload cards or ASIC‑based appliances can handle encryption and decryption at line speed, freeing the main CPU for inspection tasks. By offloading cryptographic work, the proxy reduces handshake latency and sustains higher throughput.
Steps to adopt hardware acceleration: (a) assess current SSL/TLS traffic volume, (b) select a compatible accelerator module, (c) install and integrate it with the proxy software, (d) configure the proxy to route encrypted sessions through the accelerator, and (e) benchmark before‑and‑after performance to validate gains.
- Key Benefits:
- Faster SSL/TLS handshakes
- Higher concurrent connection capacity
- Reduced CPU load extends hardware lifespan
6. Implement Real‑Time Monitoring and Auto‑Remediation
Proactive monitoring tools that track latency, queue depth, and CPU usage can trigger automated actions such as scaling out proxy instances or temporarily relaxing inspection depth when thresholds are breached. This ensures that performance degradation is addressed before users notice it.
To set up auto‑remediation: (a) define performance baselines for typical traffic, (b) configure alerts for deviation beyond 20%, (c) script scaling actions using orchestration platforms, (d) test fail‑over scenarios, and (e) document the remediation workflow for the operations team.
- Key Benefits:
- Immediate response to congestion events
- Consistent user experience across spikes
- Data‑driven adjustments reduce manual interventions
- Inspection Depth
- Old Way: Full packet inspection on all traffic
- Better Way: Selective inspection based on risk
- Result: 30–40% latency reduction
- Bandwidth Control
- Old Way: Static throttling limits for all users
- Better Way: Adaptive allocation per application
- Result: Higher throughput for critical apps
- Caching
- Old Way: One-size-fits-all cache TTL
- Better Way: Content-aware TTLs and bypass rules
- Result: Cache hit rate improves from 45% to 78%
- Proxy Placement
- Old Way: Single centralized proxy
- Better Way: Distributed edge proxies
- Result: Average round-trip time drops by 50 ms
- SSL Handling
- Old Way: Software-only decryption
- Better Way: Hardware-accelerated offload
- Result: Handshake time is cut in half
What This Means in Practice
At a regional bank in Denver, implementing selective inspection cut average page load times for the internal loan portal from 7.2 seconds to 4.1 seconds, boosting employee productivity during peak loan‑processing weeks.
In a multinational consulting firm, adaptive bandwidth allocation ensured that consultants in London could access high‑resolution project visualizations without throttling, while still keeping video‑streaming usage within budget.
A retail chain that upgraded its caching policy saw static product images served from the proxy cache 82% of the time, eliminating repeated pulls from the CDN and shaving 1.8 seconds off checkout page loads.
When a global logistics provider rolled out edge proxies in Frankfurt, Singapore, and Dallas, drivers using handheld devices experienced a 35% reduction in latency when updating shipment status, translating to faster dispatch cycles.
A healthcare provider that added SSL/TLS hardware acceleration reported that secure EMR (Electronic Medical Record) access times dropped from 3.9 seconds to 1.7 seconds, allowing clinicians to retrieve patient data more swiftly during emergencies.
Step-by-Step Action Plan
- Audit current proxy policies to identify blanket inspection rules. Understanding the baseline helps pinpoint unnecessary overhead.
- Classify traffic by risk and business importance. Segmentation enables selective inspection and adaptive bandwidth.
- Configure selective inspection profiles for low‑risk SaaS domains. This reduces processing time without sacrificing security.
- Implement adaptive bandwidth rules that prioritize mission‑critical applications. Prioritization ensures essential services stay fast.
- Fine‑tune cache expiration settings for static assets. Proper caching cuts repeat requests to external servers.
- Deploy at least one edge proxy node closer to remote offices or cloud regions. Reducing physical distance trims latency.
- Enable real‑time monitoring and set auto‑remediation triggers for latency spikes. Proactive response keeps performance stable.
The Bottom Line
Corporate proxies are indispensable for security and compliance, yet they can become inadvertent speed traps when policies are overly broad or hardware is overstretched. By applying targeted inspection, adaptive bandwidth, smarter caching, distributed placement, and hardware acceleration, organizations can reclaim lost milliseconds and deliver a smoother web experience.
Modern enterprises that treat proxy performance as a continuous optimization problem will see measurable gains in employee efficiency, customer satisfaction, and overall network health. The path forward is clear: blend security with speed, and let the data speak for itself.
Contact
Missing something?
Feel free to request missing tools or give some feedback using our contact form.
Contact Us