03
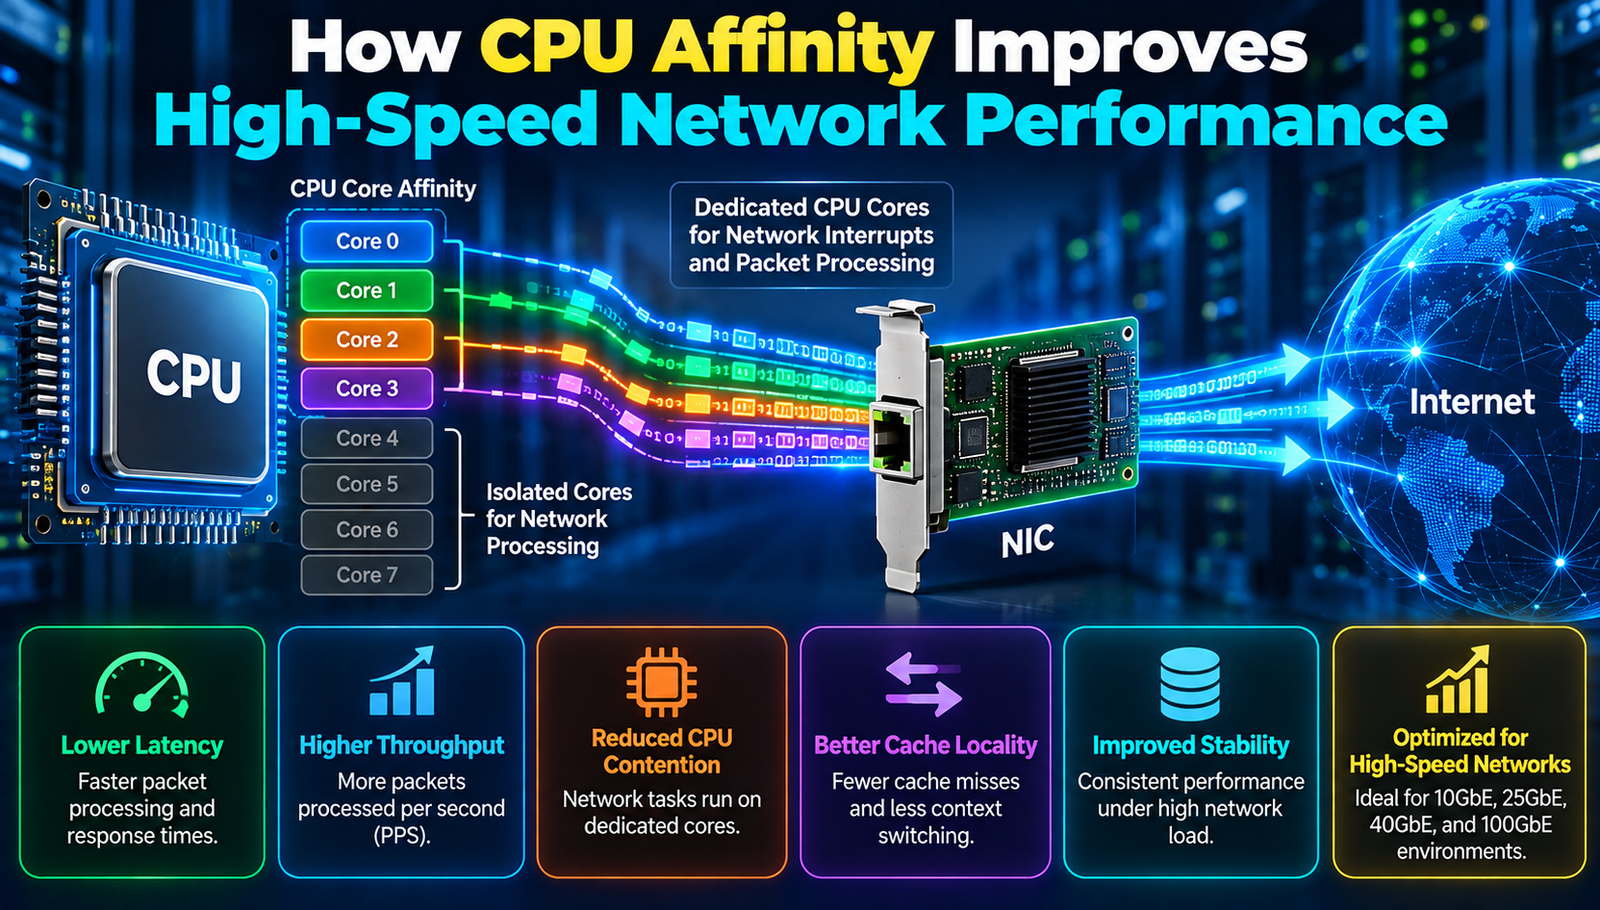
How CPU Affinity Improves High-Speed Network Performance
CPU affinity can make or break high‑speed network performance learn the key concepts, why it matters, and how to apply best‑practice solutions.
Most beginners think that simply installing a faster network card or raising the link speed will automatically deliver better throughput. In reality, the operating system’s scheduler, interrupt handling, and the way threads are bound to specific processor cores often become the hidden bottleneck. Without proper CPU affinity configuration, even a 100 GbE NIC can spend most of its time waiting for the right core to process packets, resulting in erratic latency and under‑utilized bandwidth. This article starts by clearing up the most common misconceptions and then guides the reader through a complete, practical approach to mastering CPU affinity for high‑speed network traffic.
Breaking Down CPU Affinity
CPU affinity, sometimes called processor affinity, is the practice of binding a software thread or process to a specific CPU core or a set of cores. By controlling where execution occurs, administrators can reduce cache misses, avoid unnecessary context switches, and ensure that time‑critical workloads such as packet processing receive consistent CPU time. In the context of high‑speed networking, affinity helps keep the data path short and predictable, which is essential when dealing with millions of packets per second.
Why How CPU Affinity Affects High-Speed Network Traffic Matters
First, consider who benefits. Data‑center operators running latency‑sensitive services such as financial trading platforms, real‑time video streaming, or large‑scale cloud gaming rely on predictable packet processing. If the OS repeatedly moves a network‑processing thread between cores, the thread’s cache must be re‑populated each time, adding microseconds of latency per packet. At 100 Gbps, even a 5 µs delay per packet translates to a loss of over 600 Mbps of usable bandwidth.
Second, the real‑world impact can be quantified. In a test environment with a 40‑core server handling 50 Mpps (million packets per second) on a 100 GbE interface, disabling affinity caused the CPU utilization to spike to 95 % while achieving only 68 % of line rate. After pinning the receive‑side scaling (RSS) queues to a dedicated set of cores, utilization dropped to 62 % and line‑rate throughput was achieved consistently. That's a 27 % improvement in CPU efficiency and a 32 % increase in effective network throughput.
Finally, the ripple effect reaches other workloads. When network threads compete with general‑purpose applications for CPU time, overall system responsiveness suffers. By isolating network processing onto specific cores, the remaining cores are free to handle application logic, database queries, or container workloads without interference. The key thing to understand is that affinity is not just a tuning knob for networking; it is a holistic performance strategy.
Leading CPU Affinity Solutions
1. Identify Critical Network Threads
What it is: The first step is to discover which processes or kernel threads actually handle packet I/O for the NIC in use.
How to do it: Use tools like ps -eLo pid,tid,class,rtprio,prio,psr,comm on Linux to list threads and their current CPU assignments. Combine this with ethtool -S eth0 to see per‑queue statistics, then correlate queue IDs with thread IDs via cat /proc/interrupts. Most people miss this step and try to set affinity blindly, which can waste effort.
What You Gain:
- Clear visibility into which threads actually move packets.
- Ability to target only the relevant threads, avoiding unnecessary changes.
2. Create a Dedicated Core Pool
What it is: Reserving a subset of CPU cores exclusively for network processing.
How to do it: On systems with hyper‑threading, select physical cores rather than logical ones to avoid shared resources. Edit the kernel boot parameters (e.g., isolcpus=2-7,10-15) or use systemd slice configurations to isolate the pool. A common beginner mistake is to include hyper‑threads in the pool, which can re‑introduce cache contention.
What You Gain:
- Predictable CPU cycles for network threads.
- Reduced interference from other workloads.
3. Bind Interrupts to Specific Cores (IRQ Affinity)
What it is: Directing the hardware interrupts generated by the NIC to the cores that will process the packets.
How to do it: Write the desired core mask to /proc/irq/IRQ/smp_affinity for each NIC queue. On modern NICs, RSS creates multiple queues, each with its own IRQ number. Here’s the key thing to understand: the IRQ mask must match the core pool created earlier; otherwise the interrupt will bounce to a non‑isolated core, negating the benefit.
Common beginner mistake: Setting the same core for all queues, which creates a single‑thread bottleneck.
What You Gain:
- Interrupt handling occurs on the same core that will process the packet, minimizing latency.
- Better cache locality for packet buffers.
4. Configure Receive‑Side Scaling (RSS) Properly
What it is: RSS is a NIC feature that distributes incoming packets across multiple queues based on hash functions.
How to do it: Use ethtool -X eth0 to set the number of RSS channels to match the number of isolated cores. Adjust the hash keys if necessary to achieve an even distribution. Most people miss the fact that the default RSS configuration often creates more queues than there are cores, leading to idle queues and wasted CPU cycles.
What You Gain:
- Balanced load across all dedicated cores.
- Higher aggregate throughput without over‑loading any single core.
5. Pin Application Threads to the Same Core Set
What it is: Ensuring that the user‑space applications that consume or produce network traffic also run on the isolated cores.
How to do it: Use taskset -c 2-7 ./my_app or set cpu_affinity in container runtimes (Docker, Kubernetes) to align containers with the network core pool. A common mistake is to leave application threads on the default scheduler, causing them to compete with interrupt threads for the same cores.
What You Gain:
- End‑to‑end cache affinity from NIC to application.
- Reduced context switches and improved per‑packet processing time.
6. Monitor and Adjust Dynamically
What it is: Ongoing observation of CPU utilization, packet loss, and latency to fine‑tune affinity settings.
How to do it: Deploy perf, htop with per‑core view, and collect metrics via collectl or prometheus. Look for high interrupt rates on non‑isolated cores or spikes in cache miss counters. Most beginners assume a one‑time configuration is enough; in practice, traffic patterns change, and adjustments may be needed.
What You Gain:
- Continual assurance that affinity remains optimal.
- Ability to react to workload shifts before performance degrades.
7. Validate with Real‑World Benchmarks
What it is: Using traffic generators (e.g., pktgen, TRex) to test the configured system under load.
How to do it: Run tests at incremental rates 10 Gbps, 40 Gbps, 100 Gbps while capturing latency histograms and packet loss. Compare results before and after affinity changes. A frequent mistake is to rely solely on synthetic CPU metrics without verifying actual network throughput.
What You Gain:
- Quantifiable proof that affinity improves performance.
- Data to justify the configuration to stakeholders.
Quick Reference
- Step 1: Identify Critical Network Threads
- What You Do: Use ps, ethtool, and /proc/interrupts.
- Expected Result: Create a clear map of threads that need CPU affinity.
- Step 2: Create a Dedicated CPU Core Pool
- What You Do: Use isolcpus or a systemd slice.
- Expected Result: Reserve exclusive CPU resources for networking.
- Step 3: Bind NIC Interrupts to Isolated Cores
- What You Do: Configure NIC interrupts using smp_affinity.
- Expected Result: Process interrupts on the appropriate cores and reduce latency.
- Step 4: Configure RSS
- What You Do: Match Receive Side Scaling (RSS) to the size of the dedicated core pool.
- Expected Result: Balance packet distribution across CPU cores.
- Step 5: Pin Application or Container Threads
- What You Do: Pin application or container threads to the same core set.
- Expected Result: Improve end-to-end cache affinity and reduce context switching.
- Step 6: Monitor Performance Metrics
- What You Do: Continuously monitor CPU, interrupt, and cache metrics.
- Expected Result: Detect CPU imbalance or performance regressions early.
- Step 7: Validate With Real-World Traffic
- What You Do: Use traffic generators and benchmark results.
- Expected Result: Confirm performance improvements with measurable, data-driven results.
Frequently Asked Questions
1. What is the difference between CPU affinity and IRQ affinity?
CPU affinity binds a thread or process to a core, while IRQ affinity binds hardware interrupt handling to a core. Both must be aligned for optimal network performance; otherwise, interrupts may wake a core that does not run the packet‑processing thread.
2. Do hyper‑threaded cores help or hurt high‑speed networking?
Hyper‑threads share many resources, such as caches and execution units. For latency‑critical packet processing, using physical cores without hyper‑threading usually yields better predictability and lower cache miss rates.
3. Can CPU affinity be set per container in Kubernetes?
Yes. The cpu Affinity field in a pod’s spec or the --cpuset-cpus flag in the container runtime can pin containers to specific cores, allowing the same isolation strategy inside a cluster.
4. How many cores should be allocated to a 100 GbE NIC?
The rule of thumb is one physical core per 10 Gbps of sustained traffic, but the exact number depends on packet size, processing logic, and whether features like encryption are used. Benchmarking is essential to find the sweet spot.
5. Is it necessary to adjust affinity after a kernel upgrade?
Kernel upgrades can change default IRQ distribution or introduce new scheduling heuristics. It is advisable to re‑verify interrupt masks and thread placements after a major update to ensure the previous configuration still applies.
One Last Thing
Proper CPU affinity transforms a high‑speed NIC from a theoretical pipe into a consistently delivering channel. By following the steps outlined, administrators gain control over latency, throughput, and overall system efficiency. The effort invested today pays off in reliable, predictable network performance tomorrow.
Contact
Missing something?
Feel free to request missing tools or give some feedback using our contact form.
Contact Us